
Incident response and disaster recovery are two sides of the same coin. Incident response handles the immediate threat, while disaster recovery rebuilds what was lost. Together they form your organization's safety net. Top alternatives: Cyber incident response plan, IT disaster recovery strategy, business continuity management, crisis response framework, and security incident handling.It’s 3 AM when your phone buzzes. Your production database is down. Customer data might be compromised. Your website is throwing errors. And somewhere in the back of your mind, you’re wondering if you remembered to back up last night.
Sound familiar? Whether you’re an IT manager, a business owner, or just someone who’s ever had a hard drive fail at the worst possible moment, you know the panic that comes with a major incident. That’s exactly why incident response and disaster recovery planning exist.
Open publish panel
- Post
These aren’t just buzzwords for enterprise companies with huge budgets. They’re essential strategies that protect your data, your reputation, and your sanity when things go wrong. The difference between a minor disruption and a business-ending catastrophe often comes down to how prepared you are. This guide breaks down 150+ strategies for handling incidents and recovering from disasters.
Core Definitions Responses
1. Incident response is the organized approach to addressing and managing the aftermath of a security breach or cyberattack
Example: Use this when explaining the basics to a non-technical stakeholder.
Meaning: It’s your immediate action plan when something goes wrong.
2. Disaster recovery is the process of restoring your systems and data after a disruptive event
Example: Use this when discussing long-term recovery strategies.
Meaning: It’s about getting back to normal operations.
3. Incident response focuses on the immediate threat, while disaster recovery focuses on rebuilding
Example: Use this when clarifying the difference between the two.
Meaning: They’re complementary phases of the same process.
4. The primary goal of incident response is to contain the damage and prevent further spread
Example: Use this when training your security team.
Meaning: Containment is the first priority during an active incident.
5. Disaster recovery planning involves creating a documented, structured approach to restoring operations
Example: Use this when developing your organization’s DR plan.
Meaning: It’s a proactive measure, not a reactive one.
6. Incident response is measured in minutes and hours, while disaster recovery is measured in days and weeks
Example: Use this when setting expectations with leadership.
Meaning: The timescales are fundamentally different.
7. Business continuity encompasses both incident response and disaster recovery
Example: Use this when explaining the big picture to executives.
Meaning: It’s the umbrella term for keeping your business running.
8. An incident is any event that disrupts or threatens to disrupt normal operations
Example: Use this when defining what triggers your response plan.
Meaning: Incidents range from minor glitches to major outages.
9. A disaster is an incident that causes significant disruption and requires substantial recovery efforts
Example: Use this when determining whether to activate your DR plan.
Meaning: Disasters exceed your normal incident response capabilities.
10. Recovery time objective (RTO) is the maximum acceptable time before systems must be restored
Example: Use this when setting recovery priorities.
Meaning: RTO defines how quickly you need to be back online.
11. Recovery point objective (RPO) is the maximum acceptable amount of data loss measured in time
Example: Use this when determining backup frequency.
Meaning: RPO defines how much data you can afford to lose.
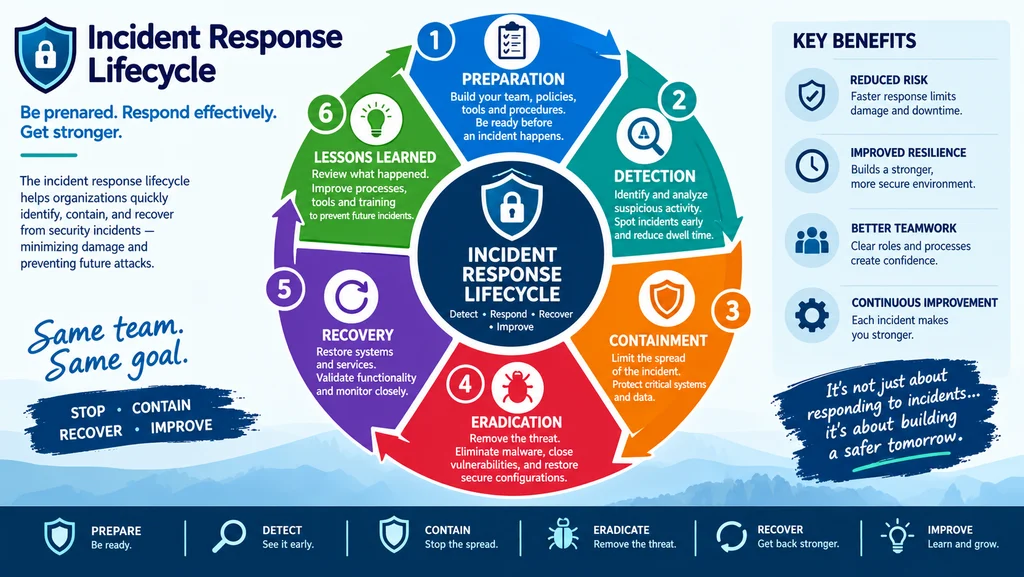
12. The incident response lifecycle includes preparation, detection, containment, eradication, recovery, and lessons learned
Example: Use this when structuring your incident response plan.
Meaning: It’s a cyclical process, not a linear one.
Preparation Responses
1. Develop an incident response plan before you need it
Example: Use this when starting your security program.
Meaning: Preparation is the foundation of effective response.
2. Identify your critical assets and prioritize them
Example: Use this when determining what to protect first.
Meaning: Not all systems are equally important.
3. Establish clear roles and responsibilities for your incident response team
Example: Use this when building your response team.
Meaning: Everyone needs to know their job during a crisis.
4. Create a communication plan for internal and external stakeholders
Example: Use this when preparing for reputational issues.
Meaning: Clear communication prevents panic and misinformation.
5. Document your disaster recovery procedures step by step
Example: Use this when building your DR playbook.
Meaning: Detailed procedures prevent confusion during stress.
6. Test your incident response plan regularly
Example: Use this when validating your preparedness.
Meaning: Untested plans often fail when needed most.
7. Conduct tabletop exercises to practice your response
Example: Use this when training your team.
Meaning: Simulation builds muscle memory for real incidents.
8. Establish relationships with external partners and vendors
Example: Use this when building your support network.
Meaning: You may need outside help during a major incident.
9. Set up monitoring and alerting systems
Example: Use this when implementing detection capabilities.
Meaning: Early detection reduces incident impact.
10. Create an incident response toolkit with essential resources
Example: Use this when preparing for rapid response.
Meaning: Having tools ready saves critical time.
11. Train all employees on basic incident reporting procedures
Example: Use this when building a security culture.
Meaning: Everyone is part of your detection network.
12. Review and update your plans regularly
Example: Use this when maintaining your preparedness.
Meaning: Plans become outdated as systems and threats evolve.
Detection and Analysis Responses
1. Monitor your systems continuously for anomalies
Example: Use this when setting up detection capabilities.
Meaning: Continuous monitoring catches issues early.
2. Establish baselines for normal system behavior
Example: Use this when configuring alerting thresholds.
Meaning: You can’t spot anomalies without knowing normal.
3. Use multiple detection methods including logs, alerts, and user reports
Example: Use this when building layered detection.
Meaning: No single detection method catches everything.
4. Investigate alerts promptly to determine if they’re real incidents
Example: Use this when triaging potential threats.
Meaning: Quick triage prevents minor issues from becoming major ones.
5. Document all findings during incident analysis
Example: Use this when investigating a security event.
Meaning: Documentation supports both response and post-incident review.
6. Determine the scope and impact of the incident
Example: Use this when assessing the severity.
Meaning: Understanding scope guides your response strategy.
7. Identify the root cause of the incident
Example: Use this when investigating what went wrong.
Meaning: Root cause analysis prevents recurrence.
8. Preserve evidence for potential forensic investigation
Example: Use this when handling security incidents.
Meaning: Evidence may be needed for legal or insurance purposes.
9. Classify incidents by severity to prioritize response
Example: Use this when allocating resources.
Meaning: Not all incidents require the same level of response.
10. Communicate findings to relevant stakeholders
Example: Use this when keeping leadership informed.
Meaning: Transparency builds trust during a crisis.
11. Use automated tools to speed up detection and analysis
Example: Use this when scaling your security operations.
Meaning: Automation handles volume while humans handle complexity.
12. Document lessons learned for future improvement
Example: Use this when closing out an incident.
Meaning: Every incident is a learning opportunity.
Containment and Eradication Responses
1. Isolate affected systems to prevent spread
Example: Use this when containing a malware outbreak.
Meaning: Containment limits the blast radius of an incident.
2. Disconnect compromised devices from the network immediately
Example: Use this when dealing with active threats.
Meaning: Network isolation prevents lateral movement.
3. Apply temporary fixes to stop ongoing damage
Example: Use this when you need to stabilize the situation.
Meaning: Short-term solutions buy time for proper fixes.
4. Preserve evidence before making changes
Example: Use this when investigating security incidents.
Meaning: Documenting the scene helps with forensics.
5. Identify and remove the root cause of the incident
Example: Use this when eradicating malware or vulnerabilities.
Meaning: Removing the cause prevents recurrence.
6. Patch vulnerabilities that allowed the incident to occur
Example: Use this when closing security gaps.
Meaning: Patching prevents the same attack from working twice.
7. Reset compromised credentials and access keys
Example: Use this when dealing with account breaches.
Meaning: Compromised credentials must be invalidated.
8. Verify that containment measures are effective
Example: Use this when confirming the threat is stopped.
Meaning: Don’t assume containment worked; verify it.
9. Coordinate with law enforcement if criminal activity is suspected
Example: Use this when dealing with cybercrime.
Meaning: Legal authorities may need to be involved.
10. Document all actions taken during containment and eradication
Example: Use this when maintaining an audit trail.
Meaning: Documentation supports post-incident review.
11. Communicate containment status to stakeholders
Example: Use this when keeping leadership informed.
Meaning: Regular updates reduce uncertainty.
12. Move to recovery phase only when the threat is fully eradicated
Example: Use this when transitioning from containment.
Meaning: Premature recovery can lead to reinfection.
Recovery Responses
1. Restore systems from clean backups
Example: Use this when recovering from data loss.
Meaning: Backups are your safety net after a disaster.
2. Verify the integrity of restored data
Example: Use this when confirming recovery success.
Meaning: Corrupted backups can cause more problems.
3. Rebuild compromised systems from scratch when necessary
Example: Use this when dealing with persistent threats.
Meaning: Sometimes clean rebuilds are safer than repairs.
4. Prioritize restoration of critical systems first
Example: Use this when resources are limited.
Meaning: Restore what matters most to the business.
5. Monitor restored systems closely for signs of reinfection
Example: Use this when confirming recovery is complete.
Meaning: Vigilance prevents secondary incidents.
6. Test restored systems before returning them to production
Example: Use this when validating recovery efforts.
Meaning: Testing catches issues before users do.
7. Communicate recovery progress to stakeholders regularly
Example: Use this when managing expectations.
Meaning: Regular updates reduce anxiety during outages.
8. Document the recovery process for future reference
Example: Use this when building institutional knowledge.
Meaning: Documentation helps with future incidents.
9. Validate that recovery objectives (RTO and RPO) were met
Example: Use this when assessing recovery effectiveness.
Meaning: Metrics show whether your plan worked.
10. Implement additional safeguards to prevent recurrence
Example: Use this when strengthening your defenses.
Meaning: Recovery is also an opportunity to improve.
11. Obtain stakeholder sign-off before declaring recovery complete
Example: Use this when formally closing the incident.
Meaning: Leadership should confirm the crisis is over.
12. Transition to normal operations gradually
Example: Use this when returning to business as usual.
Meaning: Phased returns reduce the risk of new issues.
Communication Responses
1. Designate a single point of contact for incident communications
Example: Use this when managing information flow.
Meaning: A single voice prevents confusion.
2. Prepare template messages for common incident types
Example: Use this when speeding up communication.
Meaning: Templates reduce response time during stress.
3. Communicate with transparency and honesty
Example: Use this when addressing stakeholders.
Meaning: Trust is built through honest communication.
4. Avoid technical jargon when communicating with non-technical audiences
Example: Use this when briefing executives.
Meaning: Clear language ensures understanding.
5. Provide regular updates even when there’s no new information
Example: Use this when managing a prolonged incident.
Meaning: Silence breeds speculation and anxiety.
6. Acknowledge the impact on customers and stakeholders
Example: Use this when addressing service disruptions.
Meaning: Empathy goes a long way during crises.
7. Outline the steps being taken to resolve the incident
Example: Use this when reassuring stakeholders.
Meaning: Action plans demonstrate control.
8. Set expectations for when the next update will be provided
Example: Use this when managing communication cadence.
Meaning: Predictable updates reduce uncertainty.
9. Coordinate messaging with legal and PR teams
Example: Use this when dealing with sensitive incidents.
Meaning: Consistent messaging prevents contradictions.
10. Document all communications for future reference
Example: Use this when maintaining an audit trail.
Meaning: Communication records support post-incident review.
11. Be prepared to answer difficult questions
Example: Use this when facing media or stakeholder scrutiny.
Meaning: Preparation prevents stumbling during interviews.
12. Follow up after the incident with a summary and lessons learned
Example: Use this when closing the communication loop.
Meaning: Post-incident summaries build trust and improve future response.
Testing and Validation Responses
1. Conduct regular tabletop exercises to test your incident response plan
Example: Use this when training your team.
Meaning: Discussion-based exercises reveal gaps in planning.
2. Run full-scale simulations to test your disaster recovery capabilities
Example: Use this when validating your DR plan.
Meaning: Hands-on testing builds confidence and competence.
3. Test backup restoration procedures regularly
Example: Use this when verifying your backups work.
Meaning: Untested backups are not backups.
4. Validate that your RTO and RPO targets are achievable
Example: Use this when setting recovery expectations.
Meaning: Realistic targets prevent false confidence.
5. Include external partners in your testing exercises
Example: Use this when coordinating with vendors.
Meaning: Third-party dependencies need testing too.
6. Document lessons learned from every test
Example: Use this when improving your plans.
Meaning: Testing without learning is wasted effort.
7. Rotate team members through different response roles
Example: Use this when building bench strength.
Meaning: Cross-training ensures coverage during absences.
8. Test communication channels and protocols
Example: Use this when validating your communication plan.
Meaning: Communication failures compound technical failures.
9. Simulate worst-case scenarios
Example: Use this when stress-testing your plans.
Meaning: Preparing for the worst makes the best more achievable.
10. Get executive buy-in and participation in testing
Example: Use this when building organizational commitment.
Meaning: Leadership involvement signals priority.
11. Use testing results to update your plans
Example: Use this when maintaining continuous improvement.
Meaning: Testing is only valuable if it drives change.
12. Schedule regular testing throughout the year
Example: Use this when building a testing calendar.
Meaning: Regular testing keeps skills sharp and plans current.
Post-Incident Responses
1. Conduct a post-incident review within days of resolution
Example: Use this when closing out an incident.
Meaning: Memories fade quickly; review while details are fresh.
2. Document what worked well during the response
Example: Use this when identifying strengths.
Meaning: Recognizing successes reinforces good practices.
3. Document what didn’t work and why
Example: Use this when identifying weaknesses.
Meaning: Honest assessment drives improvement.
4. Identify root causes and contributing factors
Example: Use this when analyzing what went wrong.
Meaning: Understanding causes prevents recurrence.
5. Create action items with owners and deadlines
Example: Use this when committing to improvements.
Meaning: Action items turn lessons into changes.
6. Share lessons learned with the broader organization
Example: Use this when building institutional knowledge.
Meaning: Everyone benefits from incident insights.
7. Update your incident response and disaster recovery plans
Example: Use this when incorporating lessons learned.
Meaning: Plans should evolve based on experience.
8. Provide support for team members affected by the incident
Example: Use this when addressing human impact.
Meaning: Incident response is stressful; people need support.
9. Recognize and celebrate effective response efforts
Example: Use this when building team morale.
Meaning: Recognition reinforces positive behavior.
10. Monitor for recurrence of the same or similar incidents
Example: Use this when verifying that fixes worked.
Meaning: Vigilance ensures problems stay solved.
11. Report to regulators or compliance bodies as required
Example: Use this when meeting legal obligations.
Meaning: Some incidents trigger mandatory reporting.
12. Use metrics to measure response effectiveness
Example: Use this when quantifying improvement.
Meaning: Metrics provide objective evidence of progress.
Tools and Technology Responses
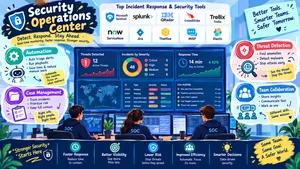
1. Use SIEM tools for centralized security monitoring
Example: Use this when building your detection capabilities.
Meaning: SIEM aggregates and correlates security events.
2. Implement endpoint detection and response (EDR) solutions
Example: Use this when protecting individual devices.
Meaning: EDR provides visibility and response at the endpoint.
3. Deploy backup and recovery software with automation
Example: Use this when streamlining recovery.
Meaning: Automation reduces recovery time and human error.
4. Use orchestration tools to automate response workflows
Example: Use this when scaling your response capabilities.
Meaning: Orchestration handles repetitive tasks efficiently.
5. Implement network segmentation to limit lateral movement
Example: Use this when containing breaches.
Meaning: Segmentation prevents attackers from moving freely.
6. Use threat intelligence feeds to stay informed about emerging threats
Example: Use this when enhancing your detection.
Meaning: Threat intelligence provides context for alerts.
7. Deploy deception technology to detect attackers early
Example: Use this when adding an extra layer of defense.
Meaning: Deception tools lure attackers into revealing themselves.
8. Use forensic tools for post-incident investigation
Example: Use this when analyzing security incidents.
Meaning: Forensics tools help uncover what happened.
9. Implement multi-factor authentication across your environment
Example: Use this when preventing credential-based attacks.
Meaning: MFA blocks unauthorized access even with stolen passwords.
10. Use cloud-based backup solutions for offsite protection
Example: Use this when protecting against physical disasters.
Meaning: Offsite backups survive local catastrophes.
11. Implement access controls and least privilege principles
Example: Use this when limiting damage from compromised accounts.
Meaning: Least privilege limits what attackers can access.
12. Use collaboration tools for incident coordination
Example: Use this when managing a distributed response team.
Meaning: Collaboration tools keep everyone connected.
FAQ
What is incident response and disaster recovery?
Incident response is the process of managing and mitigating a security incident or disruption. Disaster recovery is the process of restoring systems and data after a major disruption. Together they form your organization’s resilience strategy.
What’s the difference between incident response and disaster recovery?
Incident response focuses on the immediate threat, containing damage, and stopping the incident. Disaster recovery focuses on restoring systems and data to normal operations after the incident is contained.
Why is incident response and disaster recovery important?
Without these plans, organizations face longer outages, greater data loss, higher costs, and potential business failure. They’re essential for protecting data, maintaining customer trust, and meeting compliance requirements.
How often should I test my incident response and disaster recovery plans?
Test at least annually, but ideally more frequently. Regular testing identifies gaps and keeps skills sharp. Some organizations test quarterly or after any major change.
What’s the first step in creating an incident response and disaster recovery plan?
Start by identifying your critical assets and determining your recovery objectives (RTO and RPO). Then build your plan around protecting and restoring those assets.
Conclusion
Incident response and disaster recovery aren’t just about technology. They’re about people, processes, and preparation. When things go wrong, and they will, your ability to respond effectively and recover quickly determines whether a disruption becomes a disaster.
The good news is that you don’t have to figure it out alone. With the strategies in this guide, you can build a robust incident response and disaster recovery program that protects your organization and gives you peace of mind.
Remember, the best time to prepare for a crisis is before it happens. So start planning today. Test your plans. Update them regularly. And when the next incident hits, you’ll be ready.




3 thoughts on “150+ Best Incident Response and Disaster Recovery Strategies For 2026”